Xuzhong Wang
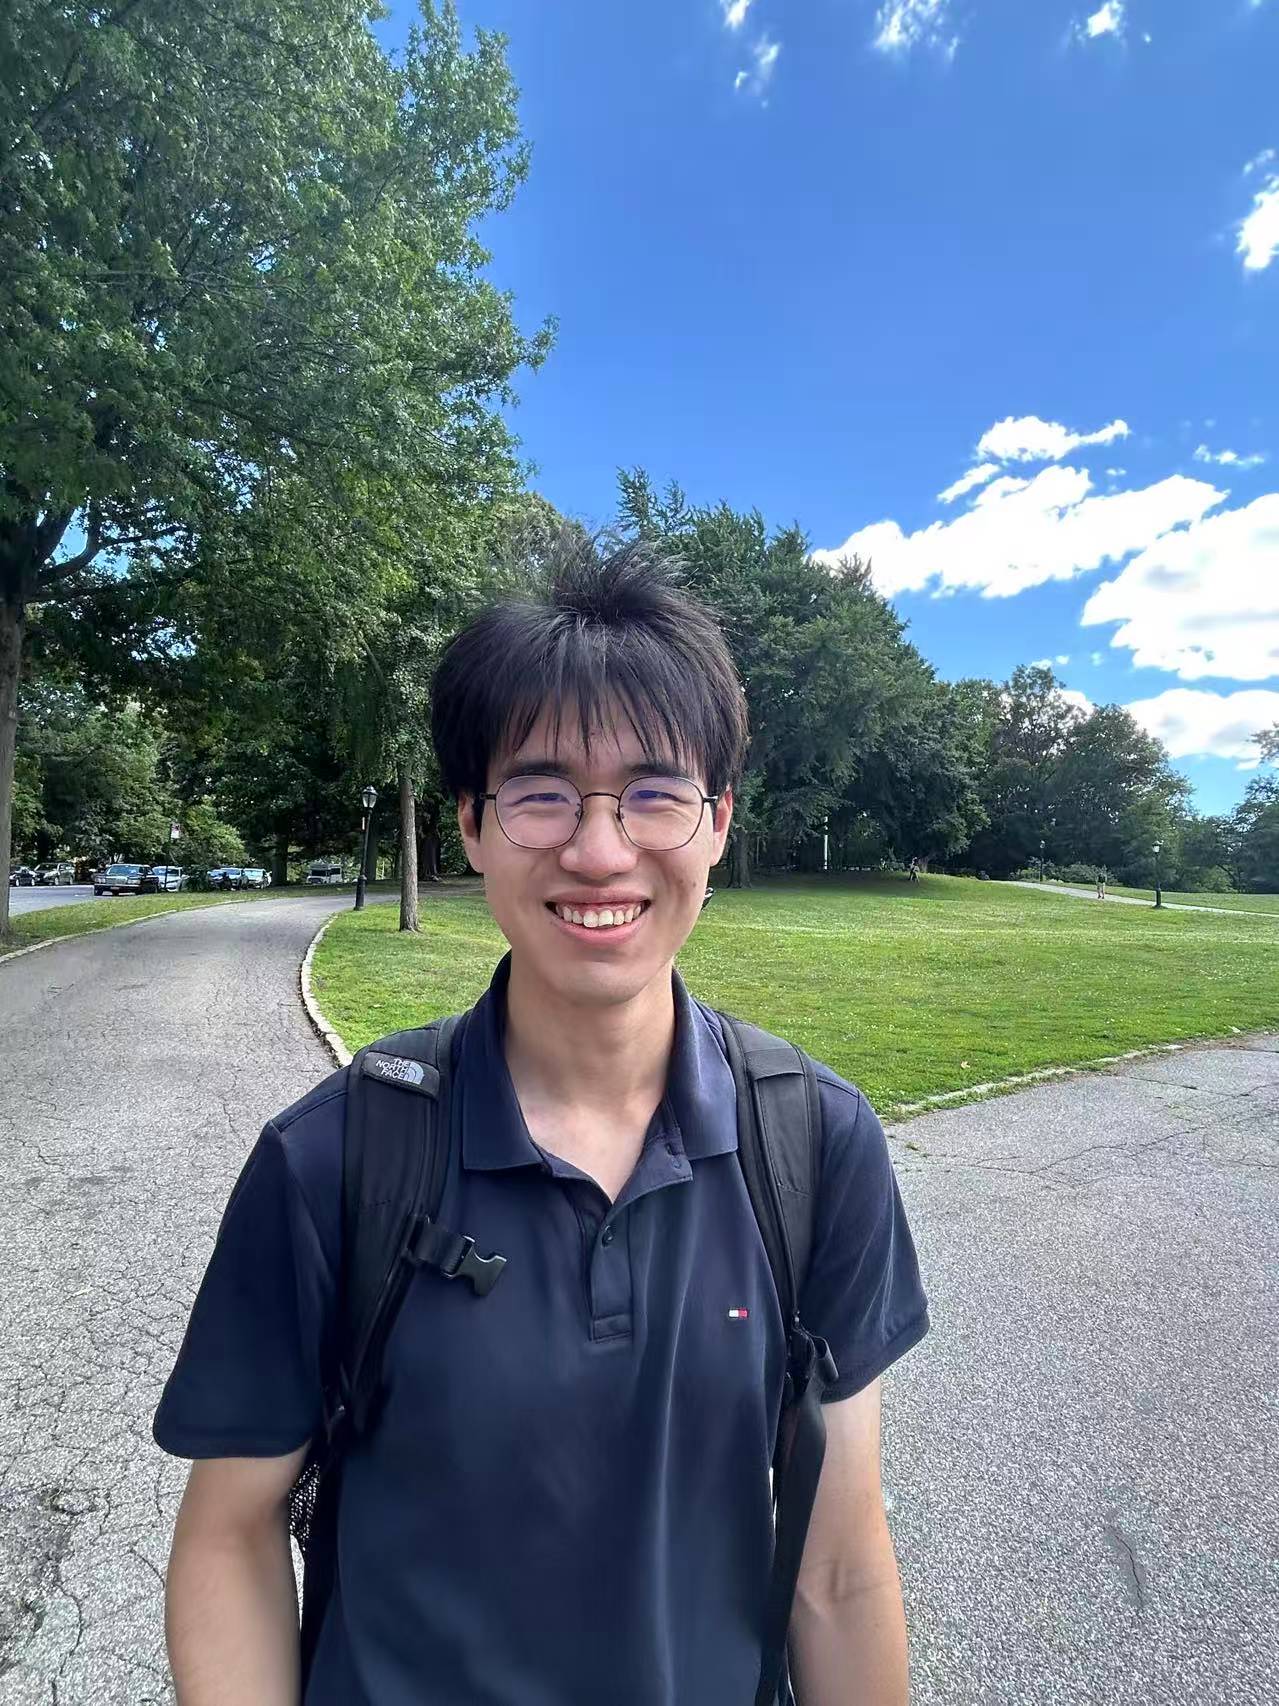
Hi! I am an undergrad at Columbia University studying Computer Science. I am currently interested in machine learning research, specifically in post-training LLMs and AI safety. Before this, I did a brief stint of research in theoretical computer science, with a focus on the diameter of graph coloring reconfiguration problems.
- Interests
- Large Language Models
- Agents
- Reinforcement Learning
- Graph Theory
Research
Broadly, I am interested in how agents can learn and adapt in complex environments. In parallel, I study and evaluate the representations in LLMs that emerge post-training—focusing on how models encode, interpret, and ground knowledge about the physical and conceptual world. Here are a few more concrete directions I am currently exploring:
-
Multi-Objective Alignment
Develope techniques to improve how models navigate through distinct objectives — accuracy, cost, and format — in reasoning, coding, and tool usage.
-
Unlearning
Develop techniques to erase the impact of certain data for ML models during training. Probe the LLM to see how "forget" acutally works in comparison to "confusion".
Selected Publications & Preprints
-
EMNLP 2026 Findings Multi-Objective RL
Towards Reliable, Generalizable, and Specific In-Context Knowledge Editing via Multi-Objective Reinforcement Learning
The complete record is on Google Scholar.
View full list on Google ScholarIt always takes longer than you expect, even when you take into account Hofstadter's Law.
— Hofstadter's Law
Industry Experience
-
AnytimeAI
ML engineer internBuilt LLM agent pipelines for legal document analysis. An agent routing tool cut inference costs ~60%.
-
Bestlink Technology
ML engineer internBuilt an OpenCV data retrieval pipeline and a LangChain-based QA agent for consulting clients.
Projects
MO-IKE
Python · PyTorchOfficial implementation of our multi-objective in-context knowledge editing work. An RL-trained retriever balances edit reliability, generality, and specificity against one another.
Akita
Go · SQLiteAn open-source computer architecture simulator I help maintain. I contributed the data recording package under Prof. Yifan Sun, for tracking simulation data across experiments.
Graph Recoloring
React · ViteAn interactive playground for graph coloring reconfiguration.